The sixth 'lab note'. I had the code audited. With some helpful scripts and an example from my 'context harness'
Tag: ChatGPT
Serious coding with LLMs. Lab notes 2026-10-21: The throttling of subscriptions by OpenAI and Anthropic is really happening
The fifth 'lab note'. This time on 'tokens' and the cost of generating them when working with LLM coding. Throttling is happening. Prepare.
Serious coding with LLMs. Lab notes 2026-10-13: Codex vs Claude on the same coding task.
The fourth 'lab note'. More on the power and Achilles' heel of "brute force trial and error with token pattern statistics" Goodbye, Codex. Hello, Limits.
Serious coding with LLMs. Lab notes 2026-10-01: Codex and Claude generate a shared analysis
The third 'lab note'. More on the power and Achilles' heel of "brute force trial and error with token pattern statistics"
Anthropic/OpenAI may be spending more than $1000 for every $100 you pay them
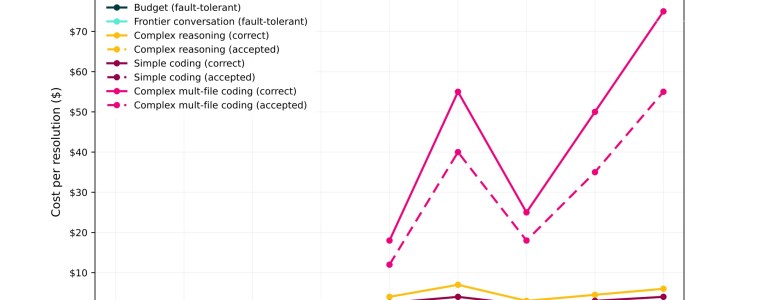
Coding with LLMs (Claude Code, OpenAI Codex) is often presented as the 'killer app' for Generative AI. But looking at data, it seems the one piece of the puzzle missing is actual cost. A quest into getting a less muddy picture about what is going on, with surprising results.
AI-generated podcast AI-slopcast
We introduce a new term: "AI-slopcast". This is a podcast that is created by Generative AI and — surprise! — is AI-slop. The victim: one of my own posts.
AI has invented a new language, and added sex to a dull office context
It turns out that AI has created a whole new language. Humans do not speak it, and they may even mistake it for talk about sex. But luckily Generative AI is able to translate it to something humans can understand (and where the sex doesn't show up).
Generative AI ‘reasoning models’ don’t reason, even if it seems they do
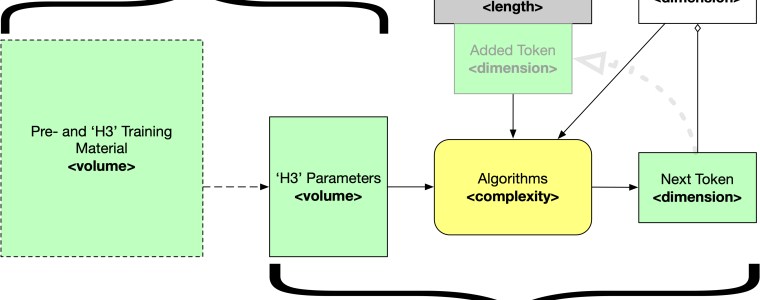
'Reasoning models' such as GPT4-o3 have become a well known member of the Generative AI family. But look inside and while they add a certain depth, at the same time they add nothing at all. Not 'reasoning' anyway. Just another 'level of indirection' when approximating. Sometimes powerful. Always costly.
Let’s call GPT and Friends: ‘Wide AI’ (and not ‘AGI’)
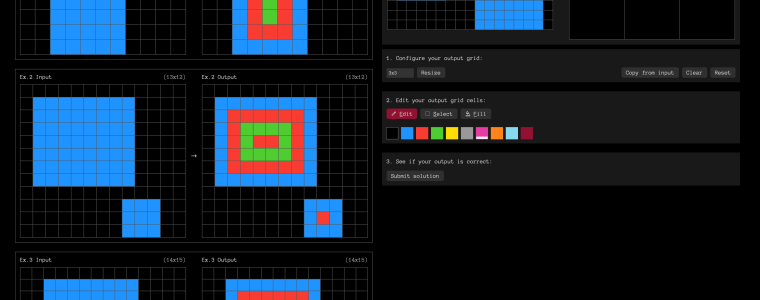
GPT-3o has done very well on the ARC-AGI-PUB benchmark. Sam Altman has also claimed OpenAI is confident that it can build Artificial General Intelligence (AGI). But that may be based on confusions around 'learning'. On the difference between narrow, general and (introducing) 'wide' AI.
When ChatGPT summarises, it actually does nothing of the kind.

One of the use cases I thought was reasonable to expect from ChatGPT and Friends (LLMs) was summarising. It turns out I was wrong. What ChatGPT isn't summarising at all, it only looks like it. What it does is something else and that something else only becomes summarising in very specific circumstances.

